Smart Routing Benchmark: Cost and Quality
A live Smart Routing benchmark compares the same prompts across routed and fixed-model requests, including classifier charges, answer checks, and latency. See where routing saved money and where it missed.
Latest news and updates from LLM Gateway

A live Smart Routing benchmark compares the same prompts across routed and fixed-model requests, including classifier charges, answer checks, and latency. See where routing saved money and where it missed.

A worked model of LLM cost optimization for a team spending $100k a month: what difficulty-based model routing saves at three traffic mixes, what the classifier costs, and the break-even point. Real catalogue prices, explicit assumptions, and the arithmetic to run on your own numbers.

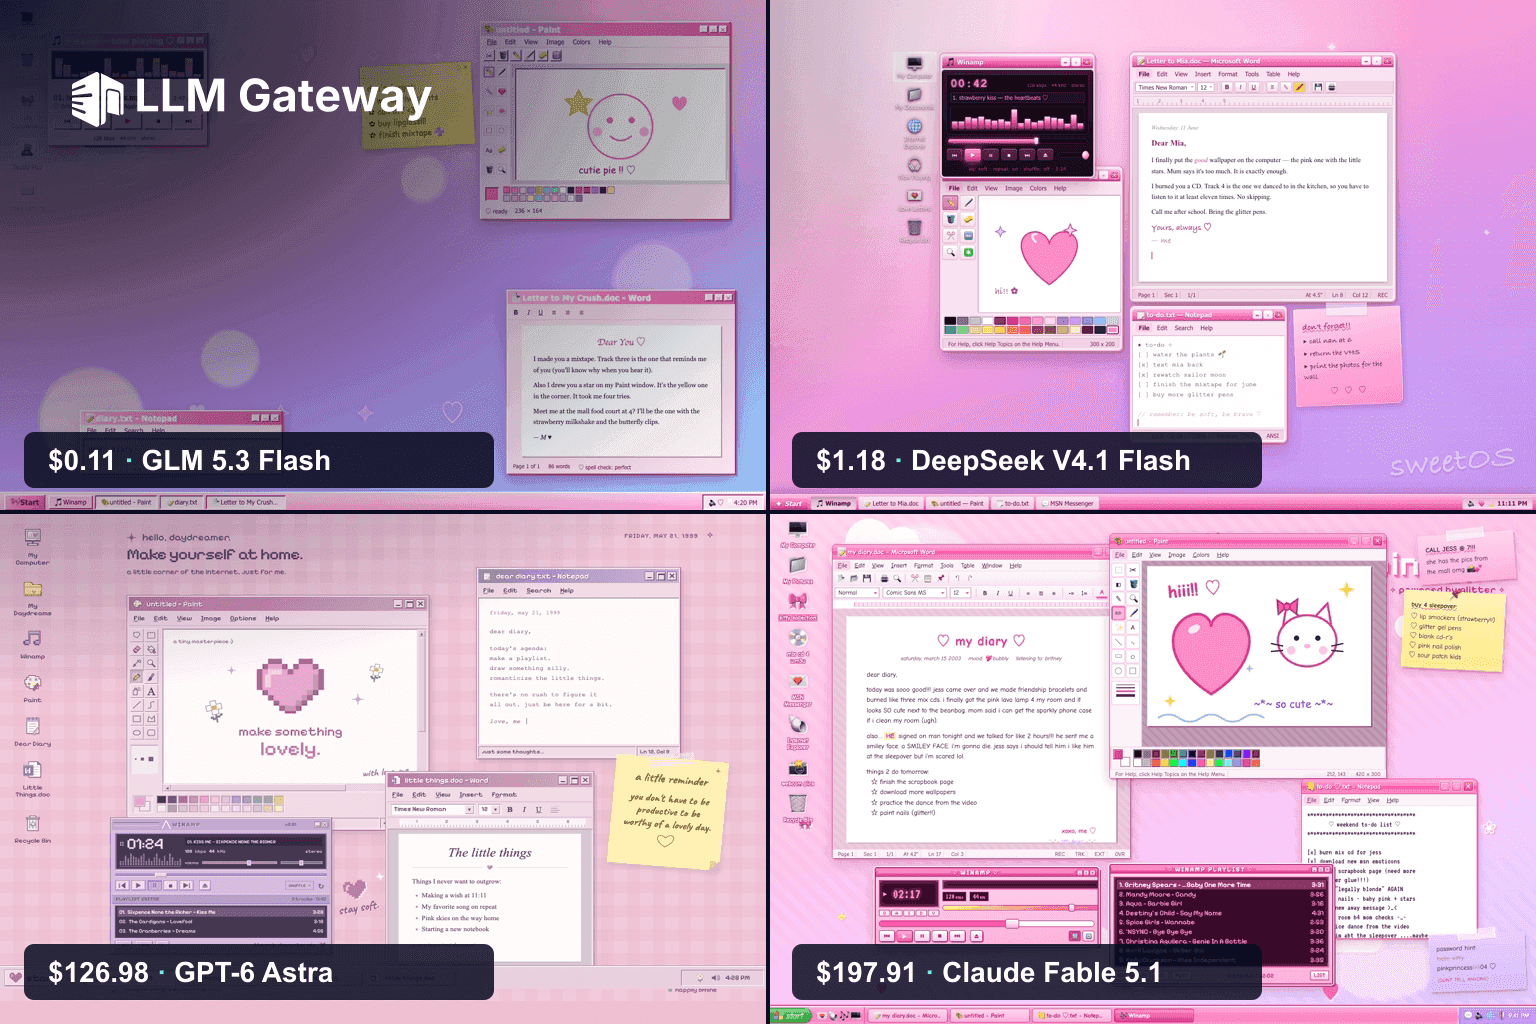
We gave six models the same coding task and measured what each one actually cost. The cheapest produced a working result for 10 cents. The most expensive spent $198 on a single index.html. This AI coding model benchmark shows where the money goes and where it stops buying quality.

A checklist for inference providers who want their LLM API listed on an AI gateway: domain ownership, an OpenAI-compatible endpoint the gateway can actually call, honest capability flags, streaming that reports usage, flat per-million pricing, and rate limits you can sustain. Written against LLM Gateway's Airside listing process.

LLM routing on LLM Gateway is an election: every provider listing a model is scored on effective price, uptime, throughput, and latency, and the lowest score wins. This guide explains the scoring from the provider's side, with the fare formula, the uptime penalty, cache-aware pricing, and the levers a carrier controls from Airside.

Cache-aware LLM routing learns cache-hit rates and token proportions from your project's recent model usage, so provider selection reflects the workload you actually run. Available automatically across plans, with explicit per-project overrides on Enterprise.

Switching off the Vercel AI Gateway used to mean rewriting how your AI SDK app resolves models — and losing provider-native web search on the way out. LLM Gateway now implements the AI SDK's own gateway protocol, so the migration is one line and your bare model strings keep working.

In the August 7 run of computesdk's independent AI gateway benchmark, LLM Gateway ranked first of six gateways with a composite score of 90.8 — driven by the tightest tail latency in the field, not the fastest median. Here's what the benchmark measures, what our numbers actually show, and how to run it yourself.

We measured AI gateway performance with an open-source TTFT benchmark: 75 cold + 75 warm interleaved runs of claude-haiku-4.5 against LLM Gateway and OpenRouter, with phase-by-phase timings and raw data published. LLM Gateway reached first token ~35% faster cold and ~34% faster warm, and here is exactly how to reproduce the numbers.

Rotating API keys shouldn't cause service interruption for production AI. Learn how LLM Gateway enables secure key rotation for both providers and the gateway.

A walkthrough of our new open-source template: a Slack bot that streams AI answers, keeps thread context, and searches the web — backed by LLM Gateway so you can switch between 200+ models with one API key.

Our new Payments SDK lets your end-users buy credits inside your app and pay per request for any model — billed through LLM Gateway, with your markup as margin. Here's how it works and how to ship it in ~40 lines.

A deep dive into the routing, retry, and failover systems that keep LLM Gateway reliable when upstream providers go down.

How we deploy our Next.js apps on Google Cloud Platform without relying on Vercel.